High-Throughput Serving
The veo_3_1 API streams stable output for apps that need quick responses and scalable model serving.
View Benchmarks

Google's state-of-the-art video generation model, built for maximum visual fidelity in final production cuts. Veo 3.1 generates high-quality 1080p video from text or image prompts with native synchronized audio — including dialogue, ambient effects, and background sound. Supports scene extension (up to 20 chained clips for 140+ second narratives), frames-to-video transitions between two images, vertical video for Shorts, and 4K upscaling.
input / per time
curl --request POST "https://apispace.ai" \
--header "Authorization: Bearer $APISPACE_API_KEY" \Combine veo_3_1 API pricing, high-throughput serving, native reasoning control, and affordable, pay-as-you-go access.
The veo_3_1 API streams stable output for apps that need quick responses and scalable model serving.
Model parameters help you tune veo_3_1 for structured output, deep thinking, and coding tasks.
Affordable veo_3_1 API pricing keeps high-volume experiments and production workloads easier to scale.
A familiar API format works with existing dashboards, logs, and backend workflows so teams can ship faster.
The veo_3_1 API is built for workloads that need responsive output, strong contextual control, and predictable billing for product teams.
With APISpace access to veo_3_1, teams can prototype, test, and ship model-powered features without juggling separate provider dashboards.
Start from the APISpace dashboard, top up once, generate a key, and make your first API call through one compatible endpoint.
Create your APISpace account and open the model dashboard.
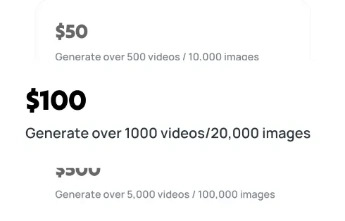
Add balance once and use it across every supported model.
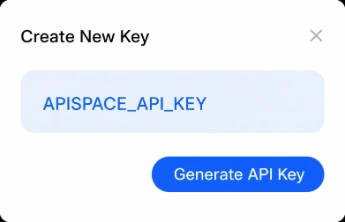
Create a key and store it securely in your application.
Send your first request through the compatible endpoint.
It is designed for request chains, coding support, and structured application workflows.
Use the model details in the dashboard for the latest context and token limits.
APISpace pricing and shared routing help teams compare cost and output quality side by side.
Use the API documentation to confirm the current tool-calling options for your endpoint.
Yes, it can support interactive applications when your latency and routing setup are tuned for it.
Reasoning behavior can be tuned through the model parameters exposed in the dashboard.
The hosted API is a managed model endpoint, not an open-source model package.